India’s Unified Lending Interface puts the data plumbing before the AI credit promise
ULI connects lenders and information providers. A practical explanation separates data availability, interpretation and a lending decision.
A dairy farmer's income may be visible to a milk collection network long before it is easy for a lender to interpret. A small business may have useful tax or transaction records but still be asked to assemble the same information repeatedly. Those gaps are a useful starting point for understanding India's Unified Lending Interface. The important development is a route between information providers and lenders, rather than a new chatbot deciding who deserves credit.
The [Reserve Bank of India's annual report for 2024–25](https://www.rbi.org.in/scripts/AnnualReportPublications.aspx?Id=1436) describes ULI as an open-architecture platform connecting lenders and data-service providers through standardised APIs. It records 44 lenders, more than 60 data services and 12 loan journeys as of 31 March 2025. Those are dated pilot figures, not a count of today's users or evidence that an AI model improved lending decisions. This article's sources were checked on 16 October 2026.
A platform that connects information, not an automatic loan approval
The distinction is central to the story. An interface can reduce the number of separate technical connections a lender must build. A risk model then uses whatever information is lawfully available and appropriate for its task. A bank can use the interface without using a generative model at all. Conversely, a sophisticated model cannot compensate for incorrect land records, missing permissions or confusion about what a transaction means.
RBI's report says the pilot began on 17 August 2023 and that the platform was renamed ULI on 26 August 2024. The [RBI Innovation Hub's 2024–25 annual report](https://rbih-website-assets.s3.ap-south-1.amazonaws.com/resources/annual-report-2024-2025.pdf) describes the same platform and maps categories such as land and crop records, milk payments, identity verification, financial data and digital documentation. Its diagram illustrates connections and possible loan journeys. It does not demonstrate that every listed source is available to every participating lender or borrower.
Consider what a milk-payment record might mean operationally. A regular receipt could help a lender investigate income that is poorly represented in conventional paperwork. But seasonality, shared household activity and interruptions can change its interpretation. The correct response to a gap is to investigate it. Treating a missing digital record as proof of no income would turn a data-access improvement into a new barrier for precisely the people an inclusion initiative hopes to reach.
This is where AI could become useful, provided the task is narrow. A system might help staff identify missing documents, reconcile formats or summarise a file for human assessment. That is an analytical proposal, not a claim that ULI itself performs these functions or that a named bank has deployed them. The distinction allows teams to discuss a genuine infrastructure development without assigning it capabilities its public description does not establish.
Consent has to survive the journey between organisations
A [2024 RBI Bulletin discussion](https://rbi.org.in/scripts/BS_ViewBulletin.aspx?Id=22851) describes the pilot's ambition in terms of consent-based data and related services. It also treats expansion and a full-scale launch as future work in that dated account. Readers should not convert that historical expectation into a statement that every lender, data source or loan product is now connected. Rollout stage is part of the factual record, not a detail to smooth away.
For a borrower, an intelligible request for information should answer practical questions. Which record is needed? Who will receive it? What happens if it is wrong or unavailable? A screen that asks for broad permission without explaining the loan task can leave the person unable to distinguish a useful connection from unnecessary collection. The benefit of common infrastructure should be less repeated friction, rather than less visibility into what a lender is doing.
For staff, the challenge shifts from manually carrying documents to understanding data provenance and exceptions. A loan officer may need to explain why a record does not match the application. An operations colleague may need a way to correct a mapping error without altering the underlying source. A model reviewer needs to know whether a feature reflects economic behaviour or merely the availability of a particular digital service. These are proposed responsibilities that follow from the design problem, not measured staffing changes.
India’s AI discussion is broader than one lending interface
The [FREE-AI committee report published by RBI in August 2025](https://m.rbi.org.in/scripts/PublicationReportDetails.aspx?ID=1306&UrlPage=) recommends an approach combining innovation with protection. It sets out seven guiding principles and 26 recommendations, including shared infrastructure, institutional capacity and assurance. It is a committee report with recommendations. This article does not treat every recommendation as an already effective legal instruction or claim that registering a use case establishes compliance.
That distinction is especially useful for financial inclusion. Better access to data can widen the set of people a lender can assess, while a poorly chosen model can still reproduce exclusion. A decision process needs a way to explain adverse or unexpected results to staff and, appropriately, to borrowers. It also needs a route for people who cannot supply the preferred digital record. A bank should not confuse a more complete dataset with an unbiased decision.
Published infrastructure counts cannot settle those questions. To understand outcomes, a lender would need to examine matters such as completed applications, abandonment, errors and the treatment of borrowers with thin digital histories. Comparison groups and changing economic conditions would matter. This article makes no claim about approval gains, lower default or faster disbursement, because the cited connection figures do not establish those results.
A proposed learning exercise: one household, two kinds of evidence
An original classroom exercise could follow an invented household applying for a small dairy-business loan. The learning file contains synthetic milk receipts, an incomplete land record and an explanation of a temporary interruption. A second file describes the same economic activity through conventional documents. No actual applicant, bank system or production ULI connection is used; all amounts and identities in the exercise would be invented and labelled accordingly.
The first team maps what each source can establish. Milk receipts might support a question about regular cash inflow, but they do not by themselves establish ownership of land or consent by another household member. The second team identifies which missing fields require clarification. Both teams should write the questions a loan officer would ask before attempting to build a score. This separates evidence collection from the decision it might later inform.
Learners can then propose a document-assistance tool that highlights discrepancies without deciding the application. They should test whether it describes the source accurately, preserves the applicant's explanation and avoids filling gaps with invented facts. A reviewer checks the proposed summary against the synthetic originals. The exercise is useful even without a language model, because the hard part is making the meaning of the records explicit.
A final discussion examines alternatives. What should happen if the data provider is unavailable? How can the applicant challenge an error? Which parts of the process should continue through a branch or another channel? Teams should describe recovery before arguing for automation. That keeps the exercise focused on service access and responsible interpretation rather than on a headline model-accuracy number detached from the borrower.
ULI is significant because lending depends on relationships between information systems as well as on risk judgements. Its public record offers concrete evidence of infrastructure development and a dated pilot footprint. The next question for AI is therefore practical: can a bank use better-connected information to make its process more understandable and accessible? That outcome has to be demonstrated in the lending journey; it cannot be inferred from the existence of an interface.
Explanatory diagram and accessible reading guide
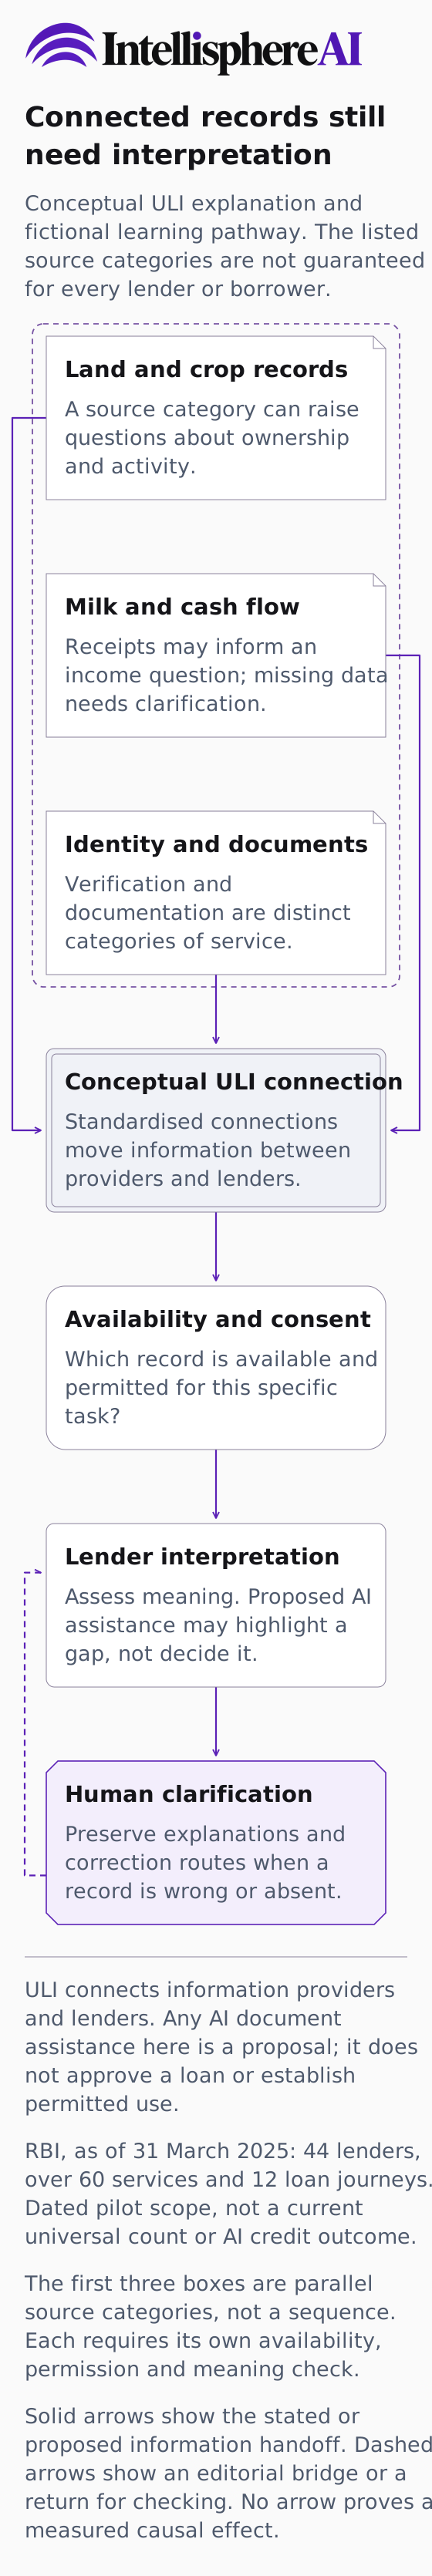
*Original educational infographic based on attributed reports and a fictional proposed exercise; not the named bank’s internal architecture, actual customer decision or measured result.*
[Open the full-size explanatory diagram](/assets/bank-india-connected-records-20261016.svg)
This original diagram explains attributed source context and a fictional learning exercise. The exercise has not been run; the diagram is not an authentic product interface, internal bank architecture or measured operational result.
Connected records still need interpretation
Conceptual ULI explanation and fictional learning pathway. The listed source categories are not guaranteed for every lender or borrower.
Land and crop records
A source category can raise questions about ownership and activity.
Milk and cash flow
Receipts may inform an income question; missing data needs clarification.
Identity and documents
Verification and documentation are distinct categories of service.
Conceptual ULI connection
Standardised connections move information between providers and lenders.
Availability and consent
Which record is available and permitted for this specific task?
Lender interpretation
Assess meaning. Proposed AI assistance may highlight a gap, not decide it.
Human clarification
Preserve explanations and correction routes when a record is wrong or absent.
ULI connects information providers and lenders. Any AI document assistance here is a proposal; it does not approve a loan or establish permitted use.
RBI, as of 31 March 2025: 44 lenders, over 60 services and 12 loan journeys. Dated pilot scope, not a current universal count or AI credit outcome.
The first three boxes are parallel source categories, not a sequence. Each requires its own availability, permission and meaning check.
Solid arrows show the stated or proposed information handoff. Dashed arrows show an editorial bridge or a return for checking. No arrow proves a measured causal effect.
Land or crop records are one conceptual input category.
Milk and cash-flow records are another conceptual input category.
Identity and document services are separate conceptual input categories.
A connection does not itself settle availability or permitted use.
An authorised available record still needs task-specific interpretation.
Missing meaning or an error is handed to human clarification.
A corrected explanation returns for assessment; it is not automatic approval.
Diagram source references
- [S07: Reports| Official Website of Reserve Bank of India](https://m.rbi.org.in/scripts/PublicationReportDetails.aspx?ID=1306&UrlPage=) — Reserve Bank of India.
- [S08: RBI Bulletin | Official Website of Reserve Bank of India](https://rbi.org.in/scripts/BS_ViewBulletin.aspx?Id=22851) — Reserve Bank of India.
- [S09: RBIH Annual Report2024–25](https://rbih-website-assets.s3.ap-south-1.amazonaws.com/resources/annual-report-2024-2025.pdf) — Reserve Bank Innovation Hub.
- [S28: Annual Report | Official Website of Reserve Bank of India](https://www.rbi.org.in/scripts/AnnualReportPublications.aspx?Id=1436) — Reserve Bank of India.